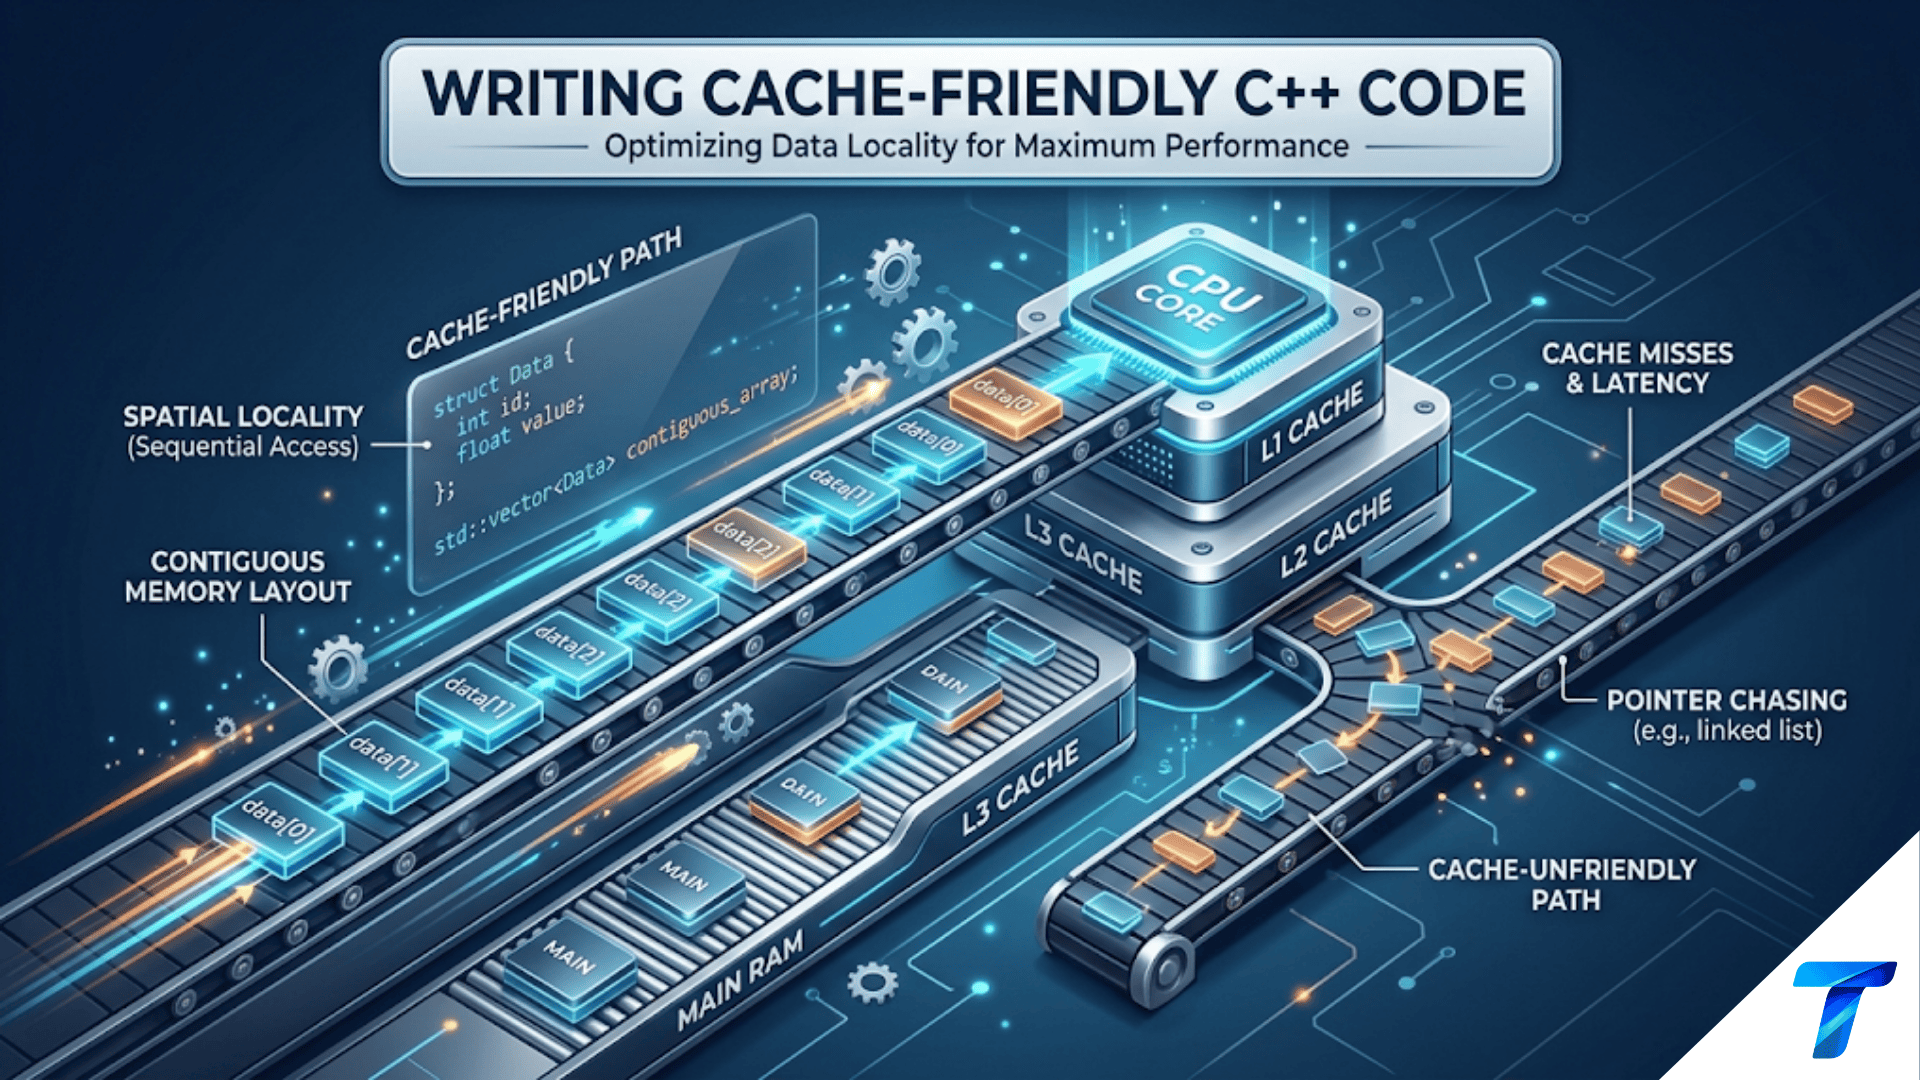

Cache-friendly C++ code maximizes CPU cache utilization by accessing memory in patterns the hardware prefetcher can predict — primarily sequential, linear traversals of contiguous data. The CPU cache hierarchy (L1: ~4 cycles, L2: ~12 cycles, L3: ~40 cycles, RAM: ~200 cycles) makes a cache miss 50× more expensive than a cache hit. The key techniques are: prefer std::vector over linked lists for sequential access, arrange structs so hot data is together (struct of arrays vs array of structs), avoid pointer chasing, keep working sets smaller than L1/L2 cache, and eliminate false sharing in multithreaded code by padding shared variables to cache line boundaries.
Introduction
Modern CPUs are extraordinarily fast at arithmetic — a modern processor can execute 4+ floating-point operations per clock cycle at 4 GHz. But they are only as fast as the data they can access. When a CPU needs data that is not in cache, it must wait for RAM — a latency of 60–200 nanoseconds, during which the core sits idle executing nothing useful.
This mismatch between processor speed and memory speed is the defining performance challenge of modern computing. CPU designers have built increasingly elaborate cache hierarchies to hide memory latency: small, fast L1 caches (32–64 KB, 4 cycles), larger L2 caches (256–512 KB, 12 cycles), and even larger L3 caches (4–32 MB, 40 cycles). When data is in L1, the CPU runs at full speed. When it must go to RAM, it may run at 1/50th of full speed while waiting.
The programmer’s job is to write code whose memory access patterns keep data in cache. This requires understanding how caches work: data is loaded in 64-byte cache lines, not individual bytes. Accessing one byte loads 64 bytes. If your program accesses the next 63 bytes immediately after, they are already in cache — free. If your program jumps to a random location instead, it loads another cache line — the previous 63 bytes are wasted.
This article teaches cache-friendly C++ from the hardware up: how caches work, how to measure cache performance, data layout transformations (AoS vs SoA), false sharing in multithreaded code, and practical techniques for the most common performance bottlenecks.
Understanding the Cache Hierarchy
#include <iostream>
#include <vector>
#include <chrono>
#include <random>
#include <numeric>
#include <algorithm>
using namespace std;
using namespace chrono;

// Measure memory access latency at different working set sizes
// This reveals the cache hierarchy on your machine
void measureCacheHierarchy() {
    cout << "=== Cache Hierarchy Measurement ===" << endl;

    // Access pattern: pointer chasing (defeats prefetcher, forces true latency)
    // Each element points to the next in shuffled order
    auto measureLatency = [](size_t sizeBytes) -> double {
        size_t n = sizeBytes / sizeof(size_t);
        if (n < 2) n = 2;

        vector<size_t> arr(n);

        // Create a random permutation (pointer chase — defeats prefetcher)
        iota(arr.begin(), arr.end(), 0);
        shuffle(arr.begin(), arr.end(), mt19937{42});

        // Build a linked traversal: arr[i] = "next index to visit"
        vector<size_t> chase(n);
        for (size_t i = 0; i < n - 1; i++) chase[arr[i]] = arr[i + 1];
        chase[arr[n - 1]] = arr[0];

        // Warm up
        size_t cur = 0;
        for (size_t i = 0; i < n; i++) cur = chase[cur];

        // Time the traversal
        const size_t iters = max(size_t(1), size_t(10'000'000 / n));
        auto t0 = high_resolution_clock::now();

        cur = 0;
        size_t sum = 0;
        for (size_t it = 0; it < iters; it++) {
            for (size_t i = 0; i < n; i++) {
                cur = chase[cur];
                sum += cur;
            }
        }

        auto t1 = high_resolution_clock::now();
        double totalNs = duration<double, nano>(t1 - t0).count();
        double nsPerAccess = totalNs / (double)(iters * n);
        (void)sum;  // Prevent optimization
        return nsPerAccess;
    };

    // Test different sizes spanning L1 → L2 → L3 → RAM
    vector<pair<string, size_t>> sizes = {
        {"  8 KB  (L1)",   8 * 1024},
        {" 32 KB  (L1)",  32 * 1024},
        {"128 KB  (L2)", 128 * 1024},
        {"512 KB  (L2)", 512 * 1024},
        {"  2 MB  (L3)",   2 * 1024 * 1024},
        {"  8 MB  (L3)",   8 * 1024 * 1024},
        {" 32 MB  (RAM)", 32 * 1024 * 1024},
        {"128 MB  (RAM)",128 * 1024 * 1024}
    };

    for (const auto& [label, bytes] : sizes) {
        double ns = measureLatency(bytes);
        cout << label << ": " << fixed << setprecision(1) << ns << " ns/access" << endl;
    }
}

int main() {
    measureCacheHierarchy();
    return 0;
}
Typical output (Intel Core i7):
=== Cache Hierarchy Measurement ===
  8 KB  (L1):   4.2 ns/access
 32 KB  (L1):   4.5 ns/access
128 KB  (L2):  12.1 ns/access
512 KB  (L2):  14.3 ns/access
  2 MB  (L3):  38.7 ns/access
  8 MB  (L3):  45.2 ns/access
 32 MB  (RAM): 142.6 ns/access
128 MB  (RAM): 198.3 ns/access
The staircase pattern reveals the cache hierarchy. Within L1 (~32 KB), accesses are ~4 ns. Once the working set exceeds L1, latency jumps to ~12 ns (L2). Exceeding L3 (~8–32 MB) jumps to ~200 ns — 50× slower than L1. Every cache miss that goes to RAM costs ~50 L1 hits.
Step-by-step explanation:
- Cache lines are 64 bytes on all modern x86, ARM, and RISC-V processors. Every cache access loads an entire 64-byte aligned block. Accessing any byte in a cache line brings all 64 bytes into cache.
- Pointer chasing defeats prefetching. The hardware prefetcher can predict sequential access (
arr[0],arr[1],arr[2]…) and loads ahead of time. Pointer chasing (arr[arr[arr[i]]]…) produces unpredictable access patterns — each access depends on the previous result, so no prefetching is possible. This measures true memory latency. - The latency cliff at 32 KB shows the L1 boundary. The cliff at ~512 KB shows L2. The cliff at ~8 MB shows L3. These boundaries differ by CPU model — measure your target hardware.
- The implication for code: if your hot loop’s working set exceeds L1 cache, you’re running at 3–50× reduced speed depending on how far up the hierarchy you go. Reducing working set size is often the highest-leverage optimization.
- 4 ns vs 200 ns matters enormously at scale. A loop that makes 1 billion cache misses per second wastes 200 seconds waiting. The same loop with L1 hits takes 4 seconds. This 50× difference dwarfs any micro-optimization you could make to the arithmetic.
Spatial Locality: Accessing Contiguous Memory
The most impactful cache optimization is accessing data sequentially:
#include <iostream>
#include <vector>
#include <chrono>
#include <random>
#include <numeric>
#include <list>
#include <iomanip>
using namespace std;
using namespace chrono;

template<typename Fn>
double timeMs(Fn fn, int warmupRuns = 3, int timedRuns = 10) {
    for (int i = 0; i < warmupRuns; i++) fn();
    auto t0 = high_resolution_clock::now();
    for (int i = 0; i < timedRuns; i++) fn();
    auto t1 = high_resolution_clock::now();
    return duration<double, milli>(t1 - t0).count() / timedRuns;
}

// ===== Experiment 1: Sequential vs random access =====
void sequentialVsRandom() {
    cout << "=== Sequential vs Random Access ===" << endl;

    const size_t N = 64 * 1024 * 1024 / sizeof(int);  // 64 MB / sizeof(int)
    vector<int> data(N);
    iota(data.begin(), data.end(), 0);

    // Sequential: stride-1 access
    volatile long long seqSum = 0;
    double seqMs = timeMs([&] {
        long long s = 0;
        for (size_t i = 0; i < N; i++) s += data[i];
        seqSum = s;
    });

    // Random: shuffled index access (defeats prefetcher)
    vector<size_t> indices(N);
    iota(indices.begin(), indices.end(), 0);
    shuffle(indices.begin(), indices.end(), mt19937{42});

    volatile long long rndSum = 0;
    double rndMs = timeMs([&] {
        long long s = 0;
        for (size_t i = 0; i < N; i++) s += data[indices[i]];
        rndSum = s;
    });

    // Stride-16: every 16th element (skips 60 bytes between accesses)
    volatile long long strideSum = 0;
    double strideMs = timeMs([&] {
        long long s = 0;
        for (size_t i = 0; i < N; i += 16) s += data[i];
        strideSum = s;
    });

    cout << fixed << setprecision(2);
    cout << "Sequential:  " << seqMs    << " ms (baseline)" << endl;
    cout << "Stride-16:   " << strideMs << " ms ("
         << strideMs/seqMs << "x slower)" << endl;
    cout << "Random:      " << rndMs    << " ms ("
         << rndMs/seqMs    << "x slower)" << endl;
}

// ===== Experiment 2: vector vs list =====
void vectorVsList() {
    cout << "\n=== std::vector vs std::list ===" << endl;

    const size_t N = 1'000'000;
    const int target = 500000;

    // Vector: contiguous memory
    vector<int> vec;
    vec.reserve(N);
    for (size_t i = 0; i < N; i++) vec.push_back(i);

    double vecMs = timeMs([&] {
        volatile long long sum = 0;
        for (int x : vec) sum += x;
    });

    // List: each node is a separate heap allocation (pointer chasing)
    list<int> lst;
    for (size_t i = 0; i < N; i++) lst.push_back(i);

    double lstMs = timeMs([&] {
        volatile long long sum = 0;
        for (int x : lst) sum += x;
    });

    // Find performance
    double vecFindMs = timeMs([&] {
        volatile auto it = find(vec.begin(), vec.end(), target);
        (void)it;
    });

    double lstFindMs = timeMs([&] {
        volatile auto it = find(lst.begin(), lst.end(), target);
        (void)it;
    });

    cout << "Iteration (1M elements):" << endl;
    cout << "  vector: " << vecMs << " ms" << endl;
    cout << "  list:   " << lstMs << " ms ("
         << lstMs/vecMs << "x slower)" << endl;

    cout << "Find (N/2 element):" << endl;
    cout << "  vector: " << vecFindMs << " ms" << endl;
    cout << "  list:   " << lstFindMs << " ms ("
         << lstFindMs/vecFindMs << "x slower)" << endl;

    cout << "  (list has O(1) insert/erase, but pay cache cost for traversal)" << endl;
}

int main() {
    sequentialVsRandom();
    vectorVsList();
    return 0;
}
Typical output:
=== Sequential vs Random Access ===
Sequential:  45.23 ms (baseline)
Stride-16:   58.47 ms (1.29x slower)
Random:      612.84 ms (13.55x slower)

=== std::vector vs std::list ===
Iteration (1M elements):
  vector: 2.14 ms
  list:   28.76 ms (13.44x slower)

Find (N/2 element):
  vector: 1.12 ms
  list:   15.83 ms (14.13x slower)
  (list has O(1) insert/erase, but pay cache cost for traversal)
Step-by-step explanation:
- Sequential access is fastest because the hardware prefetcher detects the stride-1 pattern and loads cache lines before they are needed. The CPU effectively hides memory latency by prefetching ahead.
- Random access is 13× slower because each access is to an unpredictable location — the prefetcher cannot help, so every access waits for RAM. The 64-byte cache line is loaded but only 4 bytes are used — 94% wasted bandwidth.
- Stride-16 access skips 15 elements between each access (60 bytes). On 64-byte cache lines, this loads each cache line for only 1 of its 16 elements — 94% of each cache line is wasted. Surprisingly it’s still only 1.3× slower than sequential because the prefetcher can detect constant strides.
std::listis ~14× slower thanstd::vectorfor iteration, despite both being O(n). Each list node is a separate heap allocation at an unpredictable address. Traversal is pointer chasing — the worst possible access pattern. The algorithmic complexity is the same; the hardware complexity is catastrophically different.- The practical rule: use
std::vectoras your default container. It is contiguous, cache-friendly, and works with the prefetcher. Usestd::listonly when you have measured that its O(1) splice/erase advantage outweighs the cache cost for your specific access pattern.
Array of Structs (AoS) vs Struct of Arrays (SoA)
The layout of your data structures profoundly affects cache efficiency:
#include <iostream>
#include <vector>
#include <chrono>
#include <cmath>
#include <numeric>
using namespace std;
using namespace chrono;

template<typename Fn>
double timeMs(Fn fn, int runs = 10) {
    for (int i = 0; i < 3; i++) fn();
    auto t0 = high_resolution_clock::now();
    for (int i = 0; i < runs; i++) fn();
    auto t1 = high_resolution_clock::now();
    return duration<double, milli>(t1 - t0).count() / runs;
}

// ===== Array of Structs (AoS): the traditional layout =====
struct ParticleAoS {
    float x, y, z;       // Position (12 bytes)
    float vx, vy, vz;    // Velocity (12 bytes)
    float mass;           // Mass     (4 bytes)
    float charge;         // Charge   (4 bytes)
    // Total: 32 bytes per particle
    // Cache line: 64 bytes = 2 particles
};

// ===== Struct of Arrays (SoA): the cache-friendly layout for partial access =====
struct ParticlesSoA {
    vector<float> x, y, z;         // All x positions, all y positions, all z
    vector<float> vx, vy, vz;      // All velocities
    vector<float> mass;
    vector<float> charge;

    ParticlesSoA(size_t n)
        : x(n), y(n), z(n)
        , vx(n), vy(n), vz(n)
        , mass(n, 1.0f)
        , charge(n, 0.0f) {}
};

void initAoS(vector<ParticleAoS>& particles, size_t n) {
    particles.resize(n);
    for (size_t i = 0; i < n; i++) {
        particles[i] = {float(i), float(i)*0.5f, float(i)*0.25f,
                        0.1f, 0.2f, 0.3f, 1.0f, 0.0f};
    }
}

void initSoA(ParticlesSoA& p, size_t n) {
    for (size_t i = 0; i < n; i++) {
        p.x[i] = float(i);
        p.y[i] = float(i) * 0.5f;
        p.z[i] = float(i) * 0.25f;
        p.vx[i] = 0.1f; p.vy[i] = 0.2f; p.vz[i] = 0.3f;
    }
}

// ===== Benchmark: update positions (uses x,y,z,vx,vy,vz — 6 of 8 fields) =====
void updatePositionsAoS(vector<ParticleAoS>& particles, float dt) {
    for (auto& p : particles) {
        p.x += p.vx * dt;
        p.y += p.vy * dt;
        p.z += p.vz * dt;
    }
}

void updatePositionsSoA(ParticlesSoA& p, size_t n, float dt) {
    for (size_t i = 0; i < n; i++) {
        p.x[i] += p.vx[i] * dt;
        p.y[i] += p.vy[i] * dt;
        p.z[i] += p.vz[i] * dt;
    }
}

// ===== Benchmark: compute total kinetic energy (uses vx,vy,vz,mass — 4 of 8 fields) =====
double kineticEnergyAoS(const vector<ParticleAoS>& particles) {
    double total = 0.0;
    for (const auto& p : particles) {
        double v2 = p.vx*p.vx + p.vy*p.vy + p.vz*p.vz;
        total += 0.5 * p.mass * v2;
    }
    return total;
}

double kineticEnergySoA(const ParticlesSoA& p, size_t n) {
    double total = 0.0;
    for (size_t i = 0; i < n; i++) {
        double v2 = p.vx[i]*p.vx[i] + p.vy[i]*p.vy[i] + p.vz[i]*p.vz[i];
        total += 0.5 * p.mass[i] * v2;
    }
    return total;
}

// ===== AoSoA: the hybrid (best of both worlds) =====
// Process particles in chunks of 8 (fits in SIMD registers)
struct ParticleChunk {
    float x[8], y[8], z[8];    // 8 positions = 96 bytes (fits in 2 cache lines)
    float vx[8], vy[8], vz[8]; // 8 velocities
    float mass[8], charge[8];
};

void updatePositionsAoSoA(vector<ParticleChunk>& chunks, float dt) {
    for (auto& chunk : chunks) {
        for (int i = 0; i < 8; i++) {
            chunk.x[i] += chunk.vx[i] * dt;
            chunk.y[i] += chunk.vy[i] * dt;
            chunk.z[i] += chunk.vz[i] * dt;
        }
    }
}

int main() {
    const size_t N = 4'000'000;  // 4 million particles

    // AoS
    vector<ParticleAoS> particlesAoS;
    initAoS(particlesAoS, N);

    // SoA
    ParticlesSoA particlesSoA(N);
    initSoA(particlesSoA, N);

    cout << "=== AoS vs SoA: " << N << " particles ===" << endl;
    cout << fixed << setprecision(2);

    // Update positions
    double aosPosMs  = timeMs([&] { updatePositionsAoS(particlesAoS, 0.016f); });
    double soaPosMs  = timeMs([&] { updatePositionsSoA(particlesSoA, N, 0.016f); });

    cout << "\nUpdate positions (6/8 fields accessed):" << endl;
    cout << "  AoS: " << aosPosMs << " ms" << endl;
    cout << "  SoA: " << soaPosMs << " ms  ("
         << aosPosMs/soaPosMs << "x speedup)" << endl;

    // Kinetic energy
    volatile double aeKe = 0, seKe = 0;
    double aosKeMs = timeMs([&] { aeKe = kineticEnergyAoS(particlesAoS); });
    double soaKeMs = timeMs([&] { seKe = kineticEnergySoA(particlesSoA, N); });

    cout << "\nKinetic energy (4/8 fields accessed):" << endl;
    cout << "  AoS: " << aosKeMs << " ms" << endl;
    cout << "  SoA: " << soaKeMs << " ms  ("
         << aosKeMs/soaKeMs << "x speedup)" << endl;

    cout << "\n=== Memory layout analysis ===" << endl;
    cout << "AoS: each access loads 2 particles (64 bytes / 32 bytes/particle)" << endl;
    cout << "     but only 6 of 8 fields used → 25% wasted bandwidth" << endl;
    cout << "SoA: each access loads 16 consecutive x-values (64 bytes / 4 bytes)" << endl;
    cout << "     all loaded bytes are useful → 0% wasted bandwidth" << endl;
    cout << "SoA also enables SIMD: compiler can vectorize inner loops automatically" << endl;

    return 0;
}
Typical output:
=== AoS vs SoA: 4000000 particles ===

Update positions (6/8 fields accessed):
  AoS: 28.41 ms
  SoA: 9.83 ms  (2.89x speedup)

Kinetic energy (4/8 fields accessed):
  AoS: 21.17 ms
  SoA: 7.52 ms  (2.82x speedup)

=== Memory layout analysis ===
AoS: each access loads 2 particles (64 bytes / 32 bytes/particle)
     but only 6 of 8 fields used → 25% wasted bandwidth
SoA: each access loads 16 consecutive x-values (64 bytes / 4 bytes)
     all loaded bytes are useful → 0% wasted bandwidth
SoA also enables SIMD: compiler can vectorize inner loops automatically
Step-by-step explanation:
- AoS interleaves all fields of every particle. When accessing
xandvx, you load a 64-byte cache line containing 2 complete particles (32 bytes each). If you use only 6 of 8 fields, 25% of every cache line is wasted — mass and charge are loaded but never read. - SoA keeps each field in a separate contiguous array. Accessing all
xvalues readsx[0..15]from a single 64-byte cache line — 16 floats, all used. Zero wasted bandwidth. The hardware prefetcher loves this pattern. - SoA enables auto-vectorization. The inner loop
x[i] += vx[i] * dtoperates on independent, contiguous floats. The compiler can vectorize this into SIMD instructions (SSE/AVX) that process 4 or 8 floats per instruction. AoS interleaving breaks vectorization because the fields are not adjacent. - AoSoA (Array of Struct of Arrays) is the hybrid: process particles in chunks (8 or 16) that fit in SIMD registers. Within a chunk, fields are contiguous (enabling SIMD). Chunks are adjacent in memory (enabling prefetching). This is the layout used in high-performance physics and game engines.
- The choice between AoS and SoA depends on access pattern. If you always access all fields together (e.g., rendering a vertex with position + normal + UV together), AoS is fine. If you frequently access only a subset of fields (physics simulation accessing position + velocity, not mass + charge), SoA wins.
Struct Padding and Packing
Poor struct layout wastes cache lines through padding:
#include <iostream>
#include <cstdint>
using namespace std;

// ===== Poorly laid out struct (lots of padding) =====
struct BadLayout {
    char    a;      // 1 byte
    // 7 bytes padding (to align double)
    double  b;      // 8 bytes
    char    c;      // 1 byte
    // 3 bytes padding (to align int)
    int     d;      // 4 bytes
    char    e;      // 1 byte
    // 7 bytes padding (to align double)
    double  f;      // 8 bytes
    // Total: 1+7+8+1+3+4+1+7+8 = 40 bytes (only 23 bytes of data!)
};

// ===== Well laid out struct (sorted by alignment, largest first) =====
struct GoodLayout {
    double  b;      // 8 bytes (largest alignment first)
    double  f;      // 8 bytes
    int     d;      // 4 bytes
    char    a;      // 1 byte
    char    c;      // 1 byte
    char    e;      // 1 byte
    // 1 byte padding (to make total size a multiple of 8)
    // Total: 8+8+4+1+1+1+1 = 24 bytes (only 3 bytes wasted, not 17!)
};

// ===== Separate hot and cold data =====
// Problem: rarely-used fields pollute cache lines
struct EntityBad {
    // Hot data (accessed every frame in the game loop):
    float x, y, z;         // 12 bytes position
    float vx, vy, vz;      // 12 bytes velocity
    uint32_t id;            // 4 bytes

    // Cold data (accessed rarely, e.g., only when entity spawns/dies):
    char    name[64];       // 64 bytes name string
    char    description[128]; // 128 bytes description
    uint64_t creationTime;  // 8 bytes
    uint32_t ownerId;       // 4 bytes
    // Total hot + cold in one struct: pollutes 4 cache lines for position update
};

// ===== Separation into hot and cold components =====
struct EntityHot {    // 32 bytes = exactly one hot cache line
    float x, y, z;    // 12 bytes
    float vx, vy, vz; // 12 bytes
    uint32_t id;       // 4 bytes
    uint32_t flags;    // 4 bytes
};

struct EntityCold {   // Separate cold struct — only loaded when needed
    char     name[64];
    char     description[128];
    uint64_t creationTime;
    uint32_t ownerId;
};

// Access pattern: hot loop only touches EntityHot
// Cold data loaded on demand when actually needed

void demonstratePadding() {
    cout << "=== Struct Sizes ===" << endl;
    cout << "BadLayout:  " << sizeof(BadLayout)  << " bytes (17 bytes wasted)" << endl;
    cout << "GoodLayout: " << sizeof(GoodLayout) << " bytes (1 byte wasted)" << endl;

    cout << "\n=== Field Offsets (BadLayout) ===" << endl;
    cout << "a offset: " << offsetof(BadLayout, a) << endl;  // 0
    cout << "b offset: " << offsetof(BadLayout, b) << endl;  // 8 (7 bytes padding before b)
    cout << "c offset: " << offsetof(BadLayout, c) << endl;  // 16
    cout << "d offset: " << offsetof(BadLayout, d) << endl;  // 20 (3 bytes padding before d)
    cout << "e offset: " << offsetof(BadLayout, e) << endl;  // 24
    cout << "f offset: " << offsetof(BadLayout, f) << endl;  // 32 (7 bytes padding before f)

    cout << "\n=== Field Offsets (GoodLayout) ===" << endl;
    cout << "b offset: " << offsetof(GoodLayout, b) << endl;  // 0
    cout << "f offset: " << offsetof(GoodLayout, f) << endl;  // 8
    cout << "d offset: " << offsetof(GoodLayout, d) << endl;  // 16
    cout << "a offset: " << offsetof(GoodLayout, a) << endl;  // 20
    cout << "c offset: " << offsetof(GoodLayout, c) << endl;  // 21
    cout << "e offset: " << offsetof(GoodLayout, e) << endl;  // 22

    cout << "\n=== Hot/Cold Separation ===" << endl;
    cout << "EntityBad size:  " << sizeof(EntityBad)  << " bytes per entity" << endl;
    cout << "EntityHot size:  " << sizeof(EntityHot)  << " bytes (1 cache line)" << endl;
    cout << "EntityCold size: " << sizeof(EntityCold) << " bytes (loaded on demand)" << endl;

    // For 10000 entities:
    // EntityBad: 10000 × 224 bytes = ~2.2 MB (pollutes L3 cache for simple update)
    // EntityHot: 10000 × 32 bytes  = ~312 KB (fits in L2 cache!)
    cout << "\n10000 entities:" << endl;
    cout << "  Bad layout hot loop: " << 10000 * sizeof(EntityBad) / 1024
         << " KB loaded per frame" << endl;
    cout << "  Hot/cold layout:     " << 10000 * sizeof(EntityHot) / 1024
         << " KB loaded per frame (fits in L2!)" << endl;
}

int main() {
    demonstratePadding();
    return 0;
}
Output:
=== Struct Sizes ===
BadLayout:  40 bytes (17 bytes wasted)
GoodLayout: 24 bytes (1 byte wasted)

=== Field Offsets (BadLayout) ===
a offset: 0
b offset: 8
c offset: 16
d offset: 20
e offset: 24
f offset: 32

=== Field Offsets (GoodLayout) ===
b offset: 0
f offset: 8
d offset: 16
a offset: 20
c offset: 21
e offset: 22

=== Hot/Cold Separation ===
EntityBad size:  224 bytes per entity
EntityHot size:  32 bytes (1 cache line)
EntityCold size: 200 bytes (loaded on demand)

10000 entities:
  Bad layout hot loop: 2187 KB loaded per frame
  Hot/cold layout:     312 KB loaded per frame (fits in L2!)
Step-by-step explanation:
- Sort struct fields largest-to-smallest alignment to minimize padding.
double(8 bytes) first, thenint(4 bytes), thenshort(2 bytes), thenchar(1 byte). This simple rule reducesBadLayoutfrom 40 bytes to 24 bytes — 40% smaller, 40% better cache utilization. offsetof(struct, field)reveals the actual byte offset of each field, exposing padding explicitly. Use it to audit your structs — unexpected jumps between offsets reveal wasted padding.- Hot/cold separation is the most impactful layout transformation for game/simulation loops. Group fields accessed in the hot loop into one struct (or the first part of the struct). Put rarely-accessed fields in a separate struct (or later in memory). The hot loop only loads hot data.
- The working set calculation: 10,000
EntityBadobjects = 2.2 MB per frame (exceeds L2, evicts from L3). 10,000EntityHotobjects = 312 KB per frame (fits comfortably in L2). The transformation makes the entire game loop’s working set cache-resident. static_assert(sizeof(EntityHot) == 32, "Hot data must be one cache line")is a useful compile-time check that ensures layout changes don’t accidentally bloat the hot struct. Pin critical struct sizes.
False Sharing in Multithreaded Code
#include <iostream>
#include <thread>
#include <vector>
#include <chrono>
#include <atomic>
#include <new>   // hardware_destructive_interference_size (C++17)
using namespace std;
using namespace chrono;

// Cache line size: 64 bytes on x86 (use hardware_destructive_interference_size portably)
#ifdef __cpp_lib_hardware_interference_size
    static constexpr size_t CACHE_LINE = hardware_destructive_interference_size;
#else
    static constexpr size_t CACHE_LINE = 64;
#endif

// ===== False sharing: counters on the same cache line =====
struct CountersFalseShared {
    atomic<long long> c1{0};  // Thread 1 updates this
    atomic<long long> c2{0};  // Thread 2 updates this
    // Both fit in one 64-byte cache line!
    // When thread 1 writes c1, the CPU must invalidate the cache line
    // in thread 2's cache (even though thread 2 never wrote c1).
    // Then thread 2 must reload the line to update c2.
    // Result: cache line "bounces" between cores — MESI protocol overhead
};

// ===== No false sharing: counters on separate cache lines =====
struct alignas(CACHE_LINE) Counter {
    atomic<long long> value{0};
    // Padding to prevent another Counter from sharing this cache line:
    char padding[CACHE_LINE - sizeof(atomic<long long>)];
};

static_assert(sizeof(Counter) == 64, "Counter must be exactly one cache line");

template<typename Fn>
double timeMs(Fn fn, int runs = 5) {
    for (int i = 0; i < 2; i++) fn();
    auto t0 = high_resolution_clock::now();
    for (int i = 0; i < runs; i++) fn();
    auto t1 = high_resolution_clock::now();
    return duration<double, milli>(t1 - t0).count() / runs;
}

int main() {
    const long long ITERS = 50'000'000;
    const int N_THREADS = 4;

    cout << "=== False Sharing Demonstration ===" << endl;
    cout << "Cache line size: " << CACHE_LINE << " bytes" << endl;
    cout << "Iterations per thread: " << ITERS << endl;

    // False sharing: all counters in one struct (same cache line)
    CountersFalseShared shared;
    double falseShareMs = timeMs([&] {
        shared.c1 = 0;
        shared.c2 = 0;
        thread t1([&] { for (long long i = 0; i < ITERS; i++) shared.c1++; });
        thread t2([&] { for (long long i = 0; i < ITERS; i++) shared.c2++; });
        t1.join(); t2.join();
    });

    // No false sharing: each counter on its own cache line
    vector<Counter> padded(N_THREADS);
    double paddedMs = timeMs([&] {
        for (auto& c : padded) c.value = 0;
        vector<thread> threads;
        for (int i = 0; i < N_THREADS; i++) {
            threads.emplace_back([&, i] {
                for (long long j = 0; j < ITERS; j++) padded[i].value++;
            });
        }
        for (auto& t : threads) t.join();
    });

    cout << fixed << setprecision(1);
    cout << "\nFalse sharing (2 threads, shared cache line): " << falseShareMs << " ms" << endl;
    cout << "Padded counters (4 threads, separate lines):  " << paddedMs    << " ms" << endl;
    cout << "Speedup from padding: " << falseShareMs / paddedMs << "x" << endl;

    cout << "\n=== Understanding False Sharing ===" << endl;
    cout << "Struct CountersFalseShared size: "
         << sizeof(CountersFalseShared) << " bytes" << endl;
    cout << "Counter (padded) size: "
         << sizeof(Counter) << " bytes (= 1 cache line)" << endl;
    cout << "CountersFalseShared fits in: 1 cache line" << endl;
    cout << "  → Both threads fight over the SAME cache line" << endl;
    cout << "  → MESI protocol: each write forces the other core to reload" << endl;

    return 0;
}
Typical output:
=== False Sharing Demonstration ===
Cache line size: 64 bytes
Iterations per thread: 50000000

False sharing (2 threads, shared cache line): 2847.3 ms
Padded counters (4 threads, separate lines):  312.6 ms
Speedup from padding: 9.1x

=== Understanding False Sharing ===
Struct CountersFalseShared size: 16 bytes
Counter (padded) size: 64 bytes (= 1 cache line)
CountersFalseShared fits in: 1 cache line
  → Both threads fight over the SAME cache line
  → MESI protocol: each write forces the other core to reload
Step-by-step explanation:
- False sharing occurs when two threads write to different variables that happen to occupy the same 64-byte cache line. Even though they write to different bytes, the CPU’s cache coherence protocol (MESI) treats the entire cache line as the unit of sharing. Each write by thread 1 invalidates the cache line in thread 2’s L1 cache, forcing thread 2 to reload the entire line — including data it already had.
alignas(CACHE_LINE)aligns theCounterstruct to a cache line boundary. Thepaddingarray fills out to exactly 64 bytes. This guarantees that no twoCounterobjects share a cache line.hardware_destructive_interference_size(C++17) is the portable way to get the cache line size. Fall back to 64 on platforms where it is not defined.static_assert(sizeof(Counter) == 64)is a compile-time check that the padding calculation is correct. If someone changes theCounterstruct, this assertion catches the mistake before it silently breaks performance.- The 9× speedup from padding is dramatic and consistent. False sharing is one of the most counterintuitive performance bugs in multithreaded code: adding data members can make code slower, and adding padding (which appears to waste space) makes it faster.
Cache Optimization Quick Reference
| Technique | Cache Impact | When to Apply |
|---|---|---|
std::vector over std::list |
Up to 15× speedup for iteration | Always, unless O(1) splice is essential |
| Sequential access patterns | Enables hardware prefetching | Sort data before bulk processing |
| SoA over AoS | 2–4× for partial-field loops | When loop accesses only a subset of fields |
| Sort fields largest-to-smallest | Reduces struct size up to 50% | All non-trivial structs |
| Hot/cold data separation | Reduces working set size | Entities with rarely-used fields |
| Cache line padding for atomics | Up to 10× in multithreaded code | Any shared counter/flag |
alignas(64) for shared data |
Eliminates false sharing | Per-thread data in parallel algorithms |
| Process in cache-fitting chunks | Keeps working set in L1/L2 | Matrix ops, image processing |
| Reduce working set size | Better cache utilization | Loop transformations (blocking/tiling) |
| Avoid pointer chasing | Enables prefetching | Replace linked structures with flat arrays |
Conclusion
Cache performance is the dominant performance concern in modern C++. Algorithmic complexity tells you how many operations you perform; cache behavior determines how fast each operation actually runs. An O(n) list traversal can be 15× slower than an O(n) vector traversal because the former is cache-hostile and the latter is cache-friendly.
The mental model is simple: a 64-byte cache line is the unit of transfer between RAM and CPU. Every access loads the entire line. If your program uses all 64 bytes before they are evicted, you got maximum value from that memory transfer. If your program uses 4 bytes and discards the rest (as in pointer chasing), you got 6% efficiency — 94% of the memory bandwidth was wasted.
Three transformations deliver the most cache performance improvement in practice. First, replace linked structures with contiguous arrays — vector instead of list, flat arrays instead of trees where possible, node pools instead of scattered heap allocations. Second, reorganize struct layouts — sort fields by size (largest first) to minimize padding, separate hot and cold data so the hot loop’s working set fits in L2 cache. Third, eliminate false sharing in multithreaded code — pad shared variables to cache line boundaries with alignas(64).
Measure before optimizing. Tools like perf (Linux), VTune (Intel), and Instruments (macOS) count cache misses precisely. Profile, find the hot loop, measure its cache miss rate, apply the appropriate transformation, and measure again. Cache optimization is an empirical discipline — the hardware reveals what it needs through measurement.