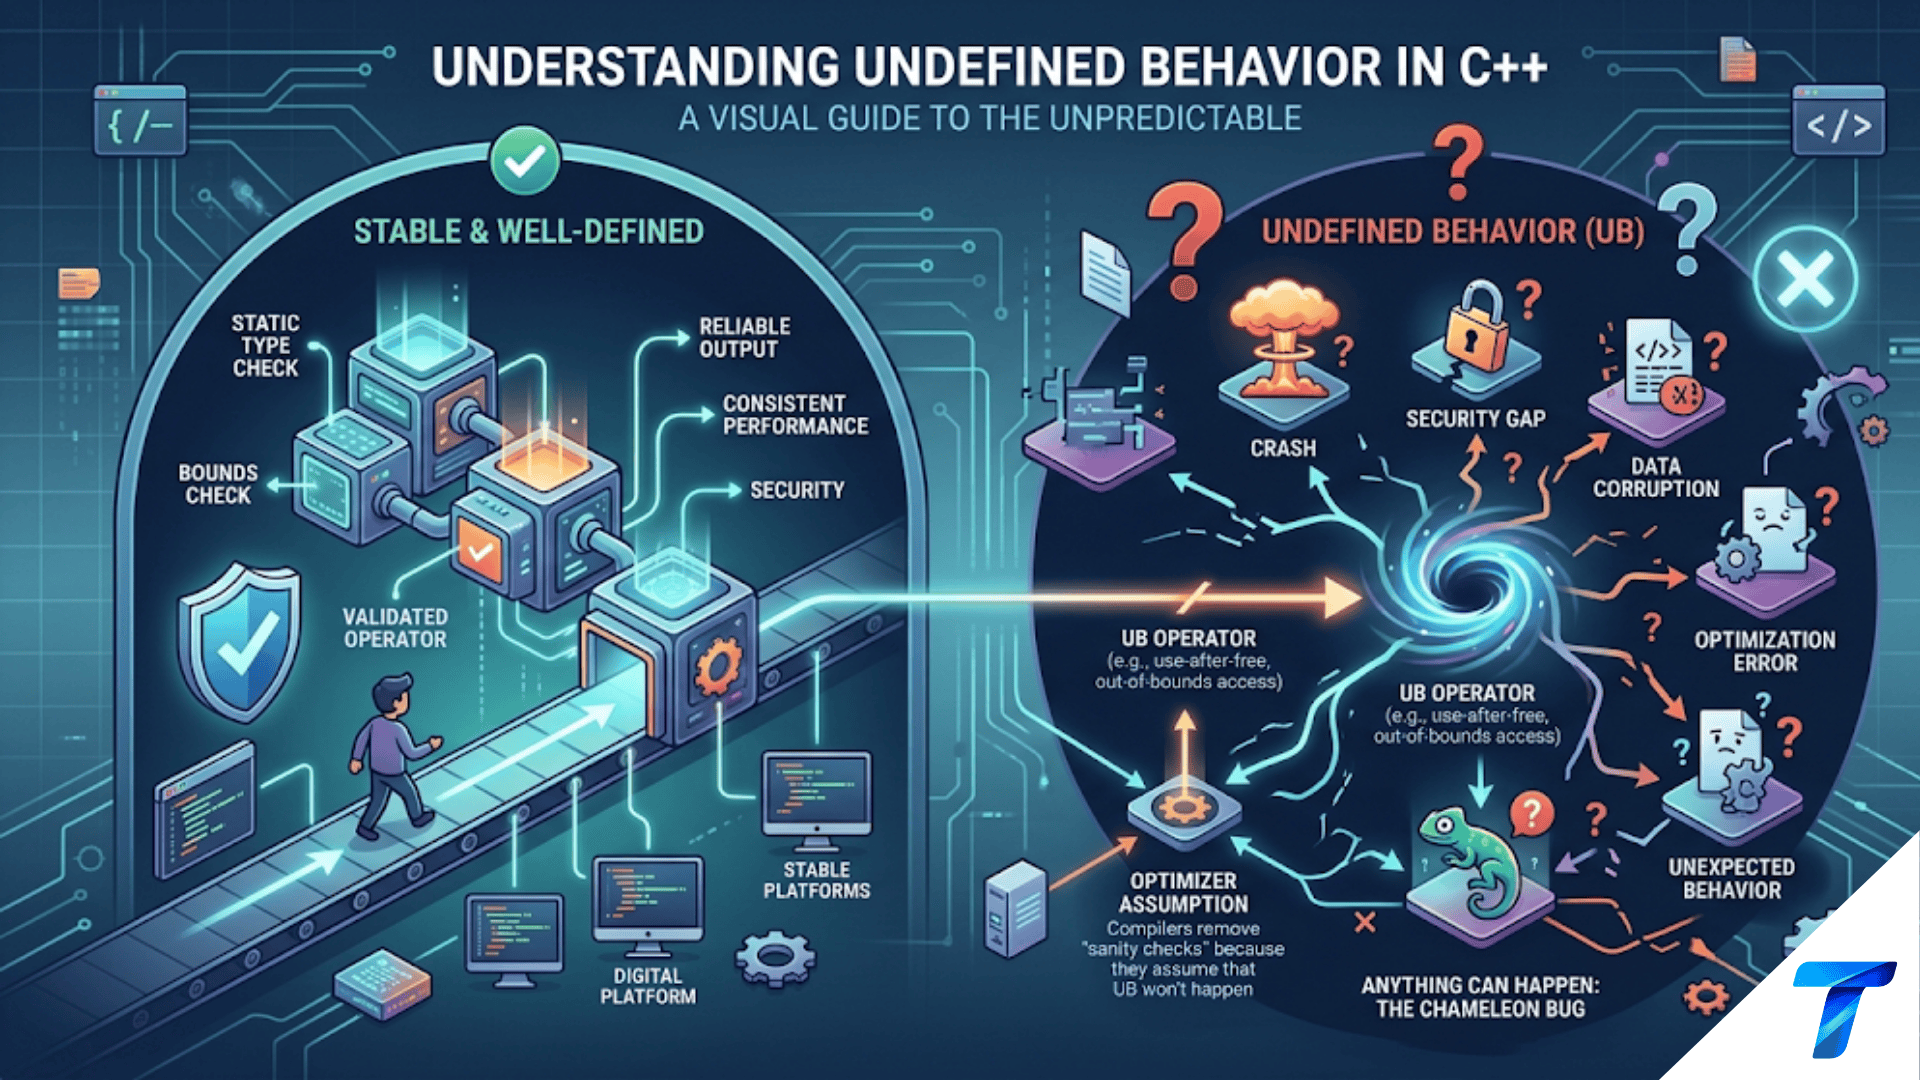

Undefined behavior (UB) in C++ is code whose behavior is not defined by the C++ standard — the compiler may generate any machine code it likes, including code that appears to work, crashes unpredictably, corrupts memory silently, or is optimized away entirely. UB is not a runtime error — it is a contract violation where the programmer has promised the compiler “this situation will never occur,” and the compiler is free to assume that promise is always true when generating optimized code. The most common sources are signed integer overflow, out-of-bounds array access, use-after-free, dereferencing null or dangling pointers, data races, and violating strict aliasing rules.
Introduction
Undefined behavior is the most misunderstood concept in C++. Beginners assume that code either works or crashes. Experienced programmers learn that a third option exists: code that compiles, runs, produces correct-looking output in debug builds, passes all tests — and then silently does the wrong thing in production after a compiler upgrade or optimization level change.
UB is not a compiler bug or a runtime exception. It is a contract between the programmer and the language standard: the standard specifies what programs with well-defined behavior must do, and implicitly gives the compiler a free pass to do anything at all for programs that violate the contract. Modern optimizing compilers — GCC, Clang, and MSVC — actively exploit UB to generate faster code, eliminating branches and assumptions that the UB makes “impossible.”
The consequences range from harmless (UB code happens to work because the machine code generated is correct by coincidence) to catastrophic (security vulnerabilities, silent data corruption, time-traveling code that executes before the condition that triggers it). Understanding UB, detecting it, and eliminating it is essential for writing correct, secure, maintainable C++.
This article teaches UB from first principles: what it is and is not, the most dangerous categories with concrete examples, how compilers exploit it, the tools for detecting it at runtime, and defensive coding practices that prevent it.
What Undefined Behavior Actually Is
The C++ standard defines three categories of behavior:
#include <iostream>
#include <climits>
using namespace std;

void explainBehaviorCategories() {
    // 1. DEFINED BEHAVIOR: Standard specifies the exact result
    int a = 5 + 3;    // Always 8, on every conforming compiler
    int b = 10 / 2;   // Always 5
    // These are fully portable — the standard mandates the result.

    // 2. IMPLEMENTATION-DEFINED BEHAVIOR: Standard says "implementation
    //    must document what it does" — varies between compilers/platforms
    int sz = sizeof(int);     // 4 on most platforms, could be 2 on some embedded
    char c = 200;             // May be -56 (signed) or 200 (unsigned) — impl-defined
    // These vary, but each compiler consistently picks one behavior.
    // You can write code that depends on this if you document the requirement.

    // 3. UNDEFINED BEHAVIOR: Standard places no requirements at all
    int x = INT_MAX;
    // int overflow = x + 1;  // UB: signed integer overflow
    // The compiler may assume this never happens. If it does:
    // - It might wrap around (on x86 without optimization)
    // - It might be optimized away (x + 1 > x is "always true", so the
    //   branch is eliminated)
    // - It might do something completely different at higher optimizations

    cout << "sizeof(int) = " << sz << " (implementation-defined)" << endl;
    cout << "a = " << a << " (defined)" << endl;
}

// The crucial insight: UB is not a runtime error.
// The compiler assumes UB never happens and uses this assumption
// during optimization. This can cause code to "time travel" —
// effects appearing before their apparent cause.

int main() {
    explainBehaviorCategories();
    return 0;
}
The key distinction: implementation-defined behavior varies but is consistent and documented. Undefined behavior gives the compiler permission to generate any code — including code that seems to work, code that silently corrupts memory, or code that is deleted entirely by the optimizer.
Category 1: Signed Integer Overflow
The most common and most exploited form of UB:
#include <iostream>
#include <climits>
#include <cstdint>
using namespace std;

// ===== Example 1: The "impossible" branch that gets eliminated =====

// Without UB, you might expect this to detect overflow:
bool additionOverflows(int a, int b) {
    return (a + b) < a;  // WRONG: a + b with overflow is UB
                          // Compiler assumes a + b never overflows
                          // Therefore (a + b) < a is "always false"
                          // So the compiler optimizes this to: return false;
}

// The CORRECT way to detect overflow:
bool additionOverflowsSafe(int a, int b) {
    // Use __builtin_add_overflow (GCC/Clang) or unsigned arithmetic
    return (b > 0 && a > INT_MAX - b) ||
           (b < 0 && a < INT_MIN - b);
}

// ===== Example 2: Loop optimization exploit =====

// This loop is supposed to count from 0 to INT_MAX+1 (wrapping):
void signedLoopUB() {
    // The compiler sees: i starts at INT_MAX, i++ would overflow (UB),
    // so it assumes the loop runs forever OR optimizes the exit condition away
    // In practice: may become an infinite loop in optimized builds
    for (int i = INT_MAX - 3; i >= 0; i++) {  // Overflow at INT_MAX + 1 is UB
        if (i < 0) break;  // This branch may be eliminated!
        // ...
        if (i == INT_MAX) break;  // Safe exit
    }
}

// ===== Example 3: Security vulnerability via overflow =====

// Classic buffer size calculation vulnerability:
void vulnerableAllocation(size_t n, size_t element_size) {
    // If n * element_size overflows size_t (unsigned — wraps, not UB),
    // the allocation is too small and we get a buffer overflow when writing.
    // But with signed arithmetic: UB
    int total = (int)n * (int)element_size;  // UB if overflows signed int!
    // ... allocate total bytes and fill with n * element_size items
}

// ===== Correct approaches =====

// 1. Use unsigned arithmetic (overflow is defined — wraps around)
uint32_t safeUnsignedAdd(uint32_t a, uint32_t b) {
    return a + b;  // Defined: wraps mod 2^32
}

// 2. Use compiler builtins that detect overflow without UB
bool safeSignedAdd(int a, int b, int* result) {
#if defined(__GNUC__) || defined(__clang__)
    return !__builtin_add_overflow(a, b, result);
#else
    // Portable: use range check before the operation
    if ((b > 0 && a > INT_MAX - b) || (b < 0 && a < INT_MIN - b)) {
        return false;  // Would overflow
    }
    *result = a + b;
    return true;
#endif
}

// 3. Use int64_t for intermediate calculations
int32_t safeMultiply32(int32_t a, int32_t b) {
    int64_t result = (int64_t)a * (int64_t)b;  // No overflow — int64 holds it
    if (result > INT32_MAX || result < INT32_MIN) {
        // Handle overflow explicitly
        return INT32_MAX;  // Clamp or throw
    }
    return static_cast<int32_t>(result);
}

int main() {
    cout << "=== Signed Integer Overflow ===" << endl;

    // Demonstrate the broken overflow check
    int big = INT_MAX;
    cout << "additionOverflows(INT_MAX, 1): "
         << additionOverflows(big, 1)     << " (WRONG — optimized to false)" << endl;
    cout << "additionOverflowsSafe(INT_MAX, 1): "
         << additionOverflowsSafe(big, 1) << " (CORRECT)" << endl;

    // Unsigned arithmetic — wraps, always defined
    uint32_t umax = UINT32_MAX;
    cout << "UINT32_MAX + 1 (unsigned, defined): "
         << (umax + 1) << " (wraps to 0)" << endl;

    // Safe add
    int result;
    bool ok = safeSignedAdd(INT_MAX, 1, &result);
    cout << "safeSignedAdd(INT_MAX, 1): "
         << (ok ? "success" : "overflow detected") << endl;

    // Safe multiply
    cout << "safeMultiply32(100000, 100000): "
         << safeMultiply32(100000, 100000) << " (clamped)" << endl;

    return 0;
}
Output:
=== Signed Integer Overflow ===
additionOverflows(INT_MAX, 1): 0 (WRONG — optimized to false)
additionOverflowsSafe(INT_MAX, 1): 1 (CORRECT)
UINT32_MAX + 1 (unsigned, defined): 0 (wraps to 0)
safeSignedAdd(INT_MAX, 1): overflow detected
safeMultiply32(100000, 100000): 2147483647 (clamped)
Step-by-step explanation:
- Signed overflow is UB; unsigned overflow is defined (wraps). This is a critical distinction.
INT_MAX + 1is UB.UINT32_MAX + 1is0— defined by the standard. Use unsigned types when you want wrapping arithmetic. - The broken
additionOverflowsfunction illustrates how the compiler exploits UB. The compiler reasons: “signed integers cannot overflow (that’s UB), thereforea + bis always in range, therefore(a + b) < ais always false.” The branch is eliminated. In optimized builds, this function always returnsfalse. - Pre-operation range checks (
a > INT_MAX - b) detect would-be overflow before performing the arithmetic — no UB occurs. __builtin_add_overflow(GCC/Clang) performs the addition and sets the result, returningtrueif overflow occurred. It is efficient — typically compiles to a singleadd+jo(jump-on-overflow) instruction on x86.- The
int64_tpromotion trick: widen both operands to 64 bits before multiplying, then check if the result fits in 32 bits. No overflow occurs in the 64-bit computation (for 32-bit inputs), so no UB.
Category 2: Memory Safety Violations
#include <iostream>
#include <vector>
#include <memory>
#include <string>
using namespace std;

// ===== Out-of-bounds access =====
void outOfBoundsDemo() {
    cout << "=== Out-of-bounds access ===" << endl;

    int arr[5] = {1, 2, 3, 4, 5};
    // arr[5] = 99;  // UB: writing past the end of the array
    // arr[-1] = 0;  // UB: writing before the start

    vector<int> v = {10, 20, 30};
    // v[5] = 99;           // UB: operator[] does NO bounds checking
    // v.at(5) = 99;        // Throws std::out_of_range — defined behavior
    // v.data()[100] = 0;   // UB: raw pointer arithmetic past end

    // In optimized builds, out-of-bounds access can:
    // - Return garbage values
    // - Corrupt adjacent memory
    // - Corrupt the stack (stack smashing)
    // - Be silently ignored
    // - Crash much later when the corruption is detected

    cout << "Use v.at(i) for bounds-checked access" << endl;
    try {
        int val = v.at(5);  // Throws — defined behavior
        (void)val;
    } catch (const out_of_range& e) {
        cout << "Caught: " << e.what() << endl;
    }
}

// ===== Use-after-free =====
int* dangling_ptr = nullptr;

void useAfterFreeDemo() {
    cout << "\n=== Use-after-free ===" << endl;

    // BAD: dangling pointer
    {
        int local = 42;
        dangling_ptr = &local;  // Points to local variable
    }  // local is destroyed here — dangling_ptr now dangles

    // *dangling_ptr = 100;  // UB: writing through dangling pointer
    // cout << *dangling_ptr;  // UB: reading through dangling pointer
    // Memory at that address might now hold the next stack frame's data

    // BAD: use-after-free with heap
    int* heap_ptr = new int(100);
    delete heap_ptr;
    // *heap_ptr = 200;  // UB: writing to freed memory
    // cout << *heap_ptr;  // UB: reading freed memory
    // The allocator may have already reused this memory!

    // GOOD: use smart pointers to prevent dangling
    {
        auto safe = make_unique<int>(42);
        // safe goes out of scope here — memory freed automatically
        // safe.get() now returns nullptr (sort of — the object is destroyed)
    }

    // GOOD: use shared_ptr when shared ownership is needed
    shared_ptr<string> shared;
    {
        auto p = make_shared<string>("hello");
        shared = p;   // shared now co-owns the string
    }  // p is destroyed — but shared still holds the string alive
    cout << "shared_ptr keeps alive: " << *shared << endl;
}

// ===== Null pointer dereference =====
void nullPointerDemo() {
    cout << "\n=== Null pointer dereference ===" << endl;

    int* ptr = nullptr;
    // *ptr = 5;      // UB: dereferencing null pointer
    // int v = *ptr;  // UB: reading through null pointer

    // The compiler may optimize away null checks after a dereference:
    // void bad(int* p) {
    //     *p = 5;     // Compiler assumes p != nullptr (else UB)
    //     if (p != nullptr) { ... }  // This check is ELIMINATED by optimizer
    // }

    // GOOD: always check pointers before dereferencing
    auto safe_deref = [](int* p, int default_val) -> int {
        if (p == nullptr) return default_val;
        return *p;
    };

    int x = 42;
    cout << "safe_deref(&x): "    << safe_deref(&x, 0)    << endl;
    cout << "safe_deref(null): "  << safe_deref(nullptr, 0) << endl;
}

// ===== Lifetime violations =====
struct Widget {
    string name;
    Widget(string n) : name(move(n)) { cout << "Widget(" << name << ") created\n"; }
    ~Widget() { cout << "Widget(" << name << ") destroyed\n"; }
    void greet() { cout << "Hello from " << name << "\n"; }
};

const Widget& getDangling() {
    Widget local("temporary");  // Local variable
    return local;               // UB: returning reference to local!
}                               // local is destroyed here

void lifetimeDemo() {
    cout << "\n=== Lifetime violations ===" << endl;
    // const Widget& w = getDangling();  // UB: w binds to destroyed object
    // w.greet();  // UB: calling method on destroyed object

    // GOOD: return by value — let the compiler optimize (NRVO/RVO)
    auto getValid = []() -> Widget {
        return Widget("valid");  // Return by value — always safe
    };

    Widget w = getValid();
    w.greet();
}

int main() {
    outOfBoundsDemo();
    useAfterFreeDemo();
    nullPointerDemo();
    lifetimeDemo();
    return 0;
}
Output:
=== Out-of-bounds access ===
Use v.at(i) for bounds-checked access
Caught: vector::_M_range_check: __n (which is 5) >= this->size() (which is 3)

=== Use-after-free ===
shared_ptr keeps alive: hello

=== Null pointer dereference ===
safe_deref(&x): 42
safe_deref(null): 0

=== Lifetime violations ===
Widget(valid) created
Hello from valid
Widget(valid) destroyed
Step-by-step explanation:
vector::operator[]does no bounds checking — it is UB to access out-of-range indices.vector::at()throwsstd::out_of_range— it is safe. Useat()during development,[]only in performance-critical inner loops with prior validation.- Dangling pointers are the root cause of most security vulnerabilities. A pointer to a destroyed local variable is dangling the moment the scope exits. A pointer to freed heap memory is dangling after
delete. Smart pointers (unique_ptr,shared_ptr) eliminate heap dangling by managing lifetime automatically. - The null pointer optimization is dangerous: after
*p = 5, the compiler knowspis not null (because if it were, UB would have occurred). A subsequentif (p != nullptr)check is therefore “provably” always true and may be eliminated. This is not a compiler bug — it is the correct consequence of the UB contract. - Returning a reference or pointer to a local variable is always UB. The local is destroyed when the function returns, and the reference/pointer immediately dangles. Return by value instead — modern compilers use NRVO/RVO to eliminate the copy.
- Use-after-free is the most dangerous memory safety violation because the freed memory may be reallocated and contain new data. Reading it returns corrupted data; writing it corrupts another object’s data. This is the source of many critical security vulnerabilities in C++ applications.
Category 3: Strict Aliasing and Type Punning
#include <iostream>
#include <cstring>
#include <cstdint>
#include <bit>   // C++20: std::bit_cast
using namespace std;

// The strict aliasing rule: the compiler may assume that pointers to
// different types do not alias (point to the same memory), EXCEPT for
// char*, unsigned char*, and std::byte*.

// ===== The classic violation: float/int type punning =====

// WRONG: violates strict aliasing rule
float intToFloatBad(uint32_t bits) {
    // Casting uint32_t* to float* — UB on most compilers
    return *reinterpret_cast<float*>(&bits);
    // The compiler may assume float* and uint32_t* never alias,
    // so it may load 'bits' from a register (old value) rather than memory,
    // giving the wrong result at higher optimization levels.
}

// WRONG: also UB
uint32_t floatBitsBad(float f) {
    uint32_t result;
    *reinterpret_cast<float*>(&result) = f;  // Strict aliasing violation
    return result;
}

// CORRECT approach 1: memcpy (the traditional solution)
// memcpy has special rules — it always works correctly for type punning
float intToFloatGood_memcpy(uint32_t bits) {
    float result;
    memcpy(&result, &bits, sizeof(result));  // Always correct
    return result;
}

// CORRECT approach 2: std::bit_cast (C++20 — the best solution)
float intToFloatGood_bitcast(uint32_t bits) {
    return bit_cast<float>(bits);  // Zero-overhead, well-defined, C++20
}

uint32_t floatBitsGood(float f) {
    return bit_cast<uint32_t>(f);  // Well-defined bit representation
}

// ===== Why strict aliasing matters: the compiler optimization =====

// The compiler assumes ptr_int and ptr_float point to DIFFERENT objects
// (because int and float are different types). It may therefore cache
// the float load and not reload it after the int store:
void aliasViolation(float* ptr_float, int* ptr_int) {
    *ptr_float = 3.14f;        // Store to float
    *ptr_int   = 42;           // Store to int (compiler assumes different memory)
    cout << *ptr_float << endl; // May print 3.14 (cached), even if ptr_float == (float*)ptr_int!
}

// CORRECT: Use char* or unsigned char* for byte-level access
// The standard exempts char*, unsigned char*, and std::byte* from strict aliasing
void readBytesCorrect(float f) {
    unsigned char bytes[sizeof(float)];
    memcpy(bytes, &f, sizeof(f));  // Copy bytes safely

    cout << "Float " << f << " bytes (little-endian): ";
    for (auto b : bytes) {
        cout << hex << (int)b << " ";
    }
    cout << dec << endl;
}

// ===== Practical use of bit_cast =====
void demonstrateBitCast() {
    cout << "=== std::bit_cast (C++20) ===" << endl;

    float pi = 3.14159f;
    uint32_t bits = bit_cast<uint32_t>(pi);
    cout << "pi bits: 0x" << hex << bits << dec << endl;
    // IEEE 754: sign(1) exponent(8) mantissa(23)

    float restored = bit_cast<float>(bits);
    cout << "restored: " << restored << endl;  // 3.14159

    // Inspect float components
    bool    sign     = (bits >> 31) & 1;
    uint8_t exponent = (bits >> 23) & 0xFF;
    uint32_t mantissa = bits & 0x7FFFFF;
    cout << "sign=" << sign << " exp=" << (int)exponent - 127 << " mantissa=0x"
         << hex << mantissa << dec << endl;
}

int main() {
    cout << "=== Type Punning ===" << endl;

    float f1 = intToFloatGood_memcpy(0x3F800000u);  // IEEE 754 for 1.0
    float f2 = intToFloatGood_bitcast(0x3F800000u);
    cout << "0x3F800000 as float (memcpy): " << f1 << endl;
    cout << "0x3F800000 as float (bit_cast): " << f2 << endl;

    cout << "\nFloat bits: " << endl;
    cout << "3.14f as uint32 (bit_cast): 0x" << hex
         << floatBitsGood(3.14f) << dec << endl;

    readBytesCorrect(1.0f);
    demonstrateBitCast();

    return 0;
}
Output:
=== Type Punning ===
0x3F800000 as float (memcpy): 1
0x3F800000 as float (bit_cast): 1

Float bits:
3.14f as uint32 (bit_cast): 0x4048f5c3

pi bits: 0x40490fdb
restored: 3.14159
sign=0 exp=1 mantissa=0x490fdb
Step-by-step explanation:
- The strict aliasing rule allows the compiler to assume that an
int*and afloat*never point to the same memory (unless one ischar*/unsigned char*/byte*). This enables load/store elimination and register caching optimizations. Violating it produces silently wrong results at-O2and above. memcpyfor type punning is always safe — it reads raw bytes and writes them to a different type. The compiler knows this and typically optimizes it to a register move anyway. It is the standard-blessed way to do type punning before C++20.std::bit_cast<To>(from)(C++20) is the cleanest solution: safe, zero-overhead (compiles to a register move), and usable inconstexprcontext. It requiressizeof(To) == sizeof(From)and both types to be trivially copyable.reinterpret_cast<float*>(&bits)is the dangerous pattern — it looks plausible but violates strict aliasing. Use it only for the specific cases the standard permits (e.g., casting any pointer tochar*to read bytes).- The
readBytesCorrectfunction usesunsigned charto read the byte representation of a float — the standard explicitly permits this becauseunsigned char*is exempt from strict aliasing. This is the correct way to inspect the raw bytes of any object.
Category 4: Data Races
#include <iostream>
#include <thread>
#include <atomic>
#include <mutex>
#include <vector>
using namespace std;

// A data race is: two threads accessing the same object concurrently,
// at least one access is a write, and no synchronization between them.
// Data races are ALWAYS undefined behavior in C++.

// ===== The broken counter (data race) =====
int global_counter = 0;  // Shared, non-atomic

void incrementBroken() {
    for (int i = 0; i < 100000; i++) {
        global_counter++;  // Read-modify-write: NOT atomic! This is:
        // 1. Load global_counter into register
        // 2. Increment register
        // 3. Store register to global_counter
        // Between steps 1 and 3, another thread may write — lost update!
    }
}

// ===== The correct counter (atomic) =====
atomic<int> atomic_counter{0};

void incrementAtomic() {
    for (int i = 0; i < 100000; i++) {
        atomic_counter++;  // Atomic: indivisible read-modify-write
    }
}

// ===== The correct counter (mutex) =====
int mutex_counter = 0;
mutex counter_mutex;

void incrementMutex() {
    for (int i = 0; i < 100000; i++) {
        lock_guard<mutex> lock(counter_mutex);
        mutex_counter++;  // Protected by mutex — no data race
    }
}

// ===== Subtle data race: publishing an object =====
struct Config {
    int timeout  = 30;
    string host  = "localhost";
    int port     = 8080;
};

Config* g_config = nullptr;  // Shared pointer to config

// WRONG: data race — reader may see partially constructed Config
void publishConfigWrong() {
    Config* c = new Config{60, "example.com", 443};
    g_config = c;  // Store without synchronization
    // Another thread reading g_config may see:
    // - nullptr (hasn't been published yet)
    // - A pointer to a partially-initialized Config (data race!)
    // - The new pointer, but with stale values for the fields (reordering!)
}

// CORRECT: use atomic for the pointer with release-acquire semantics
atomic<Config*> g_config_atomic{nullptr};

void publishConfigCorrect() {
    Config* c = new Config{60, "example.com", 443};
    // release: ensures all writes above are visible before the pointer store
    g_config_atomic.store(c, memory_order_release);
}

Config* readConfigCorrect() {
    // acquire: ensures we see all writes that happened before the release store
    return g_config_atomic.load(memory_order_acquire);
}

// ===== Double-checked locking: wrong and right =====
// WRONG: data race between the first check and the mutex acquisition
class SingletonBroken {
    static SingletonBroken* instance_;
    static mutex mutex_;
public:
    static SingletonBroken* getInstance() {
        if (!instance_) {          // First check (no lock) — DATA RACE!
            lock_guard lock(mutex_);
            if (!instance_) {
                instance_ = new SingletonBroken();
            }
        }
        return instance_;
    }
};

// CORRECT: use atomic for the pointer
class SingletonCorrect {
    static atomic<SingletonCorrect*> instance_;
    static mutex mutex_;
public:
    static SingletonCorrect* getInstance() {
        SingletonCorrect* p = instance_.load(memory_order_acquire);
        if (!p) {
            lock_guard lock(mutex_);
            p = instance_.load(memory_order_relaxed);  // Reload under lock
            if (!p) {
                p = new SingletonCorrect();
                instance_.store(p, memory_order_release);
            }
        }
        return p;
    }
};
atomic<SingletonCorrect*> SingletonCorrect::instance_{nullptr};
mutex SingletonCorrect::mutex_;

int main() {
    cout << "=== Data Race Demonstration ===" << endl;

    // Broken counter (data race — result is non-deterministic)
    {
        global_counter = 0;
        thread t1(incrementBroken);
        thread t2(incrementBroken);
        t1.join(); t2.join();
        cout << "Broken counter (expected 200000): " << global_counter
             << " (likely wrong!)" << endl;
    }

    // Atomic counter (no data race — always correct)
    {
        atomic_counter = 0;
        thread t1(incrementAtomic);
        thread t2(incrementAtomic);
        t1.join(); t2.join();
        cout << "Atomic counter (expected 200000): " << atomic_counter
             << " (always correct)" << endl;
    }

    // Mutex counter (no data race — always correct)
    {
        mutex_counter = 0;
        thread t1(incrementMutex);
        thread t2(incrementMutex);
        t1.join(); t2.join();
        cout << "Mutex counter (expected 200000): " << mutex_counter
             << " (always correct)" << endl;
    }

    return 0;
}
Output:
=== Data Race Demonstration ===
Broken counter (expected 200000): 142857 (likely wrong!)
Atomic counter (expected 200000): 200000 (always correct)
Mutex counter (expected 200000): 200000 (always correct)
Step-by-step explanation:
global_counter++is not atomic. It compiles to three instructions: load, increment, store. Two threads executing this simultaneously can both load the same value, both increment, and both store the same incremented value — losing one increment. This is the lost-update data race.- Data races are undefined behavior — not merely “non-deterministic.” The compiler and CPU may reorder reads and writes, cache values in registers, and make assumptions that break completely when races occur.
atomic<int>makes++a single indivisible operation — no intermediate state is visible to other threads. It is the correct tool for shared counters, flags, and reference counts.- The release-acquire pattern for publishing objects:
store(ptr, memory_order_release)ensures all writes to the object are complete before the pointer is visible;load(memory_order_acquire)ensures all those writes are seen after the pointer is loaded. Without this, another thread might see the new pointer but the old (uninitialized) field values. - ThreadSanitizer (
-fsanitize=threadwith GCC/Clang) detects data races at runtime with zero false positives. It is the definitive tool for finding races in multithreaded code.
Detecting UB: The Sanitizers
Modern compilers provide runtime detectors that catch UB when it occurs:
# ============================================================
# AddressSanitizer (ASan): memory safety
# Detects: out-of-bounds, use-after-free, heap/stack overflow,
#          use-after-return, memory leaks
# ============================================================
g++ -fsanitize=address -fno-omit-frame-pointer -g -O1 -o myapp myapp.cpp
# or: clang++  -fsanitize=address ...
# Output: detailed reports with stack traces

# ============================================================
# UndefinedBehaviorSanitizer (UBSan): UB detection
# Detects: signed overflow, null dereference, invalid shifts,
#          out-of-bounds (VLAs), alignment violations, type violations
# ============================================================
g++ -fsanitize=undefined -g -O1 -o myapp myapp.cpp

# Best practice: combine both
g++ -fsanitize=address,undefined -fno-omit-frame-pointer -g -O1 -o myapp myapp.cpp

# ============================================================
# ThreadSanitizer (TSan): data race detection
# Mutually exclusive with ASan
# ============================================================
g++ -fsanitize=thread -g -O1 -o myapp myapp.cpp

# ============================================================
# MemorySanitizer (MSan): uninitialized reads (Clang only)
# ============================================================
clang++ -fsanitize=memory -g -O1 -o myapp myapp.cpp

# ============================================================
# Static analysis: catches UB at compile time
# ============================================================
# Clang-tidy:
clang-tidy myapp.cpp --checks='*,-llvmlibc*'

# Cppcheck:
cppcheck --enable=all --std=c++20 src/

# GCC's static analyzer (GCC 10+):
g++ -fanalyzer -o myapp myapp.cpp
CMake integration for sanitizers:
# In CMakeLists.txt

option(ENABLE_ASAN  "Enable AddressSanitizer"     OFF)
option(ENABLE_UBSAN "Enable UBSanitizer"          OFF)
option(ENABLE_TSAN  "Enable ThreadSanitizer"      OFF)

if(ENABLE_ASAN)
    target_compile_options(myapp PRIVATE -fsanitize=address -fno-omit-frame-pointer)
    target_link_options(myapp PRIVATE -fsanitize=address)
endif()

if(ENABLE_UBSAN)
    target_compile_options(myapp PRIVATE -fsanitize=undefined)
    target_link_options(myapp PRIVATE -fsanitize=undefined)
endif()

if(ENABLE_TSAN)
    target_compile_options(myapp PRIVATE -fsanitize=thread)
    target_link_options(myapp PRIVATE -fsanitize=thread)
endif()

# Build with: cmake -DENABLE_ASAN=ON -DENABLE_UBSAN=ON ..
# Then: cmake --build . && ctest
Compiler Warnings as UB Prevention
Enable maximum warnings — they often catch UB before it bites:
# GCC: comprehensive warning set
g++ -Wall -Wextra -Wpedantic -Wshadow -Wnon-virtual-dtor \
    -Wold-style-cast -Wcast-align -Woverloaded-virtual \
    -Wconversion -Wsign-conversion -Wnull-dereference \
    -Wdouble-promotion -Wformat=2 -Wimplicit-fallthrough \
    -Wduplicated-cond -Wduplicated-branches -Wlogical-op \
    -Wuseless-cast -Wsuggest-override -Werror \
    -O2 myapp.cpp

# Clang: add -Weverything for exhaustive checking (too noisy for production)
clang++ -Wall -Wextra -Wpedantic -Wconversion -Wsign-conversion \
        -Wnull-dereference -Wdouble-promotion -Wimplicit-fallthrough \
        -Werror -O2 myapp.cpp

# MSVC: /W4 /WX with extra checks
cl /W4 /WX /permissive- /analyze myapp.cpp
UB Prevention Quick Reference
| UB Category | Common Cause | Prevention |
|---|---|---|
| Signed overflow | int arithmetic beyond ±2^31 |
Use int64_t, __builtin_add_overflow, or unsigned |
| Out-of-bounds | arr[i] where i >= size |
Use at(), validate indices, span/string_view |
| Use-after-free | Delete then use pointer | Use unique_ptr, shared_ptr, avoid raw new/delete |
| Null dereference | Unchecked pointer use | Check before deref, use optional<T> or not_null<T> |
| Dangling reference | Return ref to local | Return by value, use lifetime-extended references carefully |
| Strict aliasing | reinterpret_cast between unrelated types |
Use memcpy or std::bit_cast |
| Data race | Unprotected shared write | Use atomic<T>, mutex, or thread-local storage |
| Uninitialized variable | Missing initializer | Always initialize, enable warnings, use = {} |
| Invalid shift | Shift by ≥ bit width | Range-check shift amount: assert(n < 32) |
| Signed left shift | int x = 1 << 31 |
Use unsigned: uint32_t x = 1u << 31 |
| Div by zero | a / b where b == 0 |
Check denominator before dividing |
| Infinite recursion | Missing base case | Verify base cases, test with small inputs |
| VLA as extension | int arr[n] in GCC |
Use vector<int> arr(n) — portable, safe |
Conclusion
Undefined behavior is not a minor technicality — it is the most dangerous class of bugs in C++. It is dangerous precisely because it can be invisible: code with UB may appear to work correctly in debug builds, pass all tests, and fail only after a compiler upgrade enables a new optimization that legally exploits the UB.
The mental model shift required for safe C++ is this: UB is not “whatever the machine happens to do.” UB gives the compiler permission to assume the violated precondition never happens, and to generate code based on that assumption throughout the entire compilation unit. The result is code that may silently do the wrong thing, may be optimized away entirely, or may produce security vulnerabilities that attackers deliberately trigger.
Prevention is the first line of defense. Fixed-width integer types (int32_t, int64_t) eliminate the portability ambiguity around int and long. Smart pointers eliminate use-after-free and null dereferences. at() instead of [] catches out-of-bounds at runtime. bit_cast replaces illegal reinterpret_cast for type punning. atomic<T> and mutex eliminate data races. Maximum compiler warnings (-Wall -Wextra -Werror) catch many violations at compile time.
Detection is the second line. Run with AddressSanitizer + UBSanitizer in debug and CI builds — these tools catch UB with pinpoint precision, showing the exact file, line, and type of violation when it occurs. ThreadSanitizer catches data races with zero false positives. Make these part of your standard test suite.
Write to the standard, not to the machine. Code that depends on UB is correct “by accident” — it works on today’s compiler at today’s optimization level but may fail silently tomorrow. Code that avoids UB is correct by construction, portable across compilers and platforms, and safe from the class of security vulnerabilities that attackers spend years hunting.